Real-World Data Engineering Case Study: Fraud Detection Pipelines
A fraud detection pipeline turns payment events and supporting data into fast, trustworthy signals that help a business approve, review, or decline transactions. Effective fraud detection pipelines connect reliable data, fresh features, scoring, and feedback.
We’ll use a clearly labeled illustrative case study, not a real company’s results, to show how those pieces work together.
Key Takeaways
- Define approval, decline, and review policies before choosing tools or building a model.
- Combine streaming signals with batch data when each supports the payment decision.
- Track precision, recall, false-positive rate, decision latency, and pipeline availability together.
- Treat missing features, duplicate events, and delayed fraud labels as normal engineering problems.
- Plan fallback decisions, incident ownership, privacy controls, and replay before production launch.
Quick summary: Build around the payment decision first. Capture events, create useful signals, score risk, and record the outcome. Then use confirmed fraud outcomes and operational monitoring to improve the system.
Key takeaway: Treat each payment decision as a traceable record. When you can connect its inputs, policy, outcome, and later fraud label, you can diagnose problems and improve the pipeline with evidence.
Quick promise: You’ll have a practical launch framework: define failure behavior, assign ownership, test replay, and connect payment decisions to later outcomes before expanding the system.
Real-World Data Engineering Case Study: Fraud Detection Pipelines
Illustrative scenario: An online payment service sees suspicious payment attempts across customer accounts. Some involve repeated purchases or unfamiliar devices. Legitimate customers also change devices and make unusual purchases, so blocking everything unusual would hurt the business.
The goal is to catch risky payments while limiting false declines. Checkout also needs a timely answer.
Start with the transaction and the decision it needs
A payment event contains a transaction ID, amount, currency, timestamp, account ID, and merchant ID. Device and location signals add context when available.
The service needs one outcome: approve, decline, or send for review. Review requires a defined payment state, such as holding the transaction pending investigation.
Before picking tools, agree on the decision deadline, acceptable business risk, and review capacity. An event log, such as Apache Kafka’s event streams, supports recording and replaying events for downstream processing.
Set measures that show whether the system helps
Precision asks: of the payments flagged as fraud, how many were fraudulent? Recall asks: of all fraudulent payments, how many did the system catch?
The false-positive rate measures legitimate payments incorrectly flagged. Track false declines separately because review doesn’t always mean rejection.
Decision latency measures response time. Pipeline availability measures whether the system can deliver decisions when needed.
Here’s the thing: confirmed fraud labels arrive later. Queue growth and scoring errors give immediate operational feedback. They don’t prove whether fraud detection improved.
How a fraud detection pipeline moves data from payment to decision
The architecture follows the decision path:
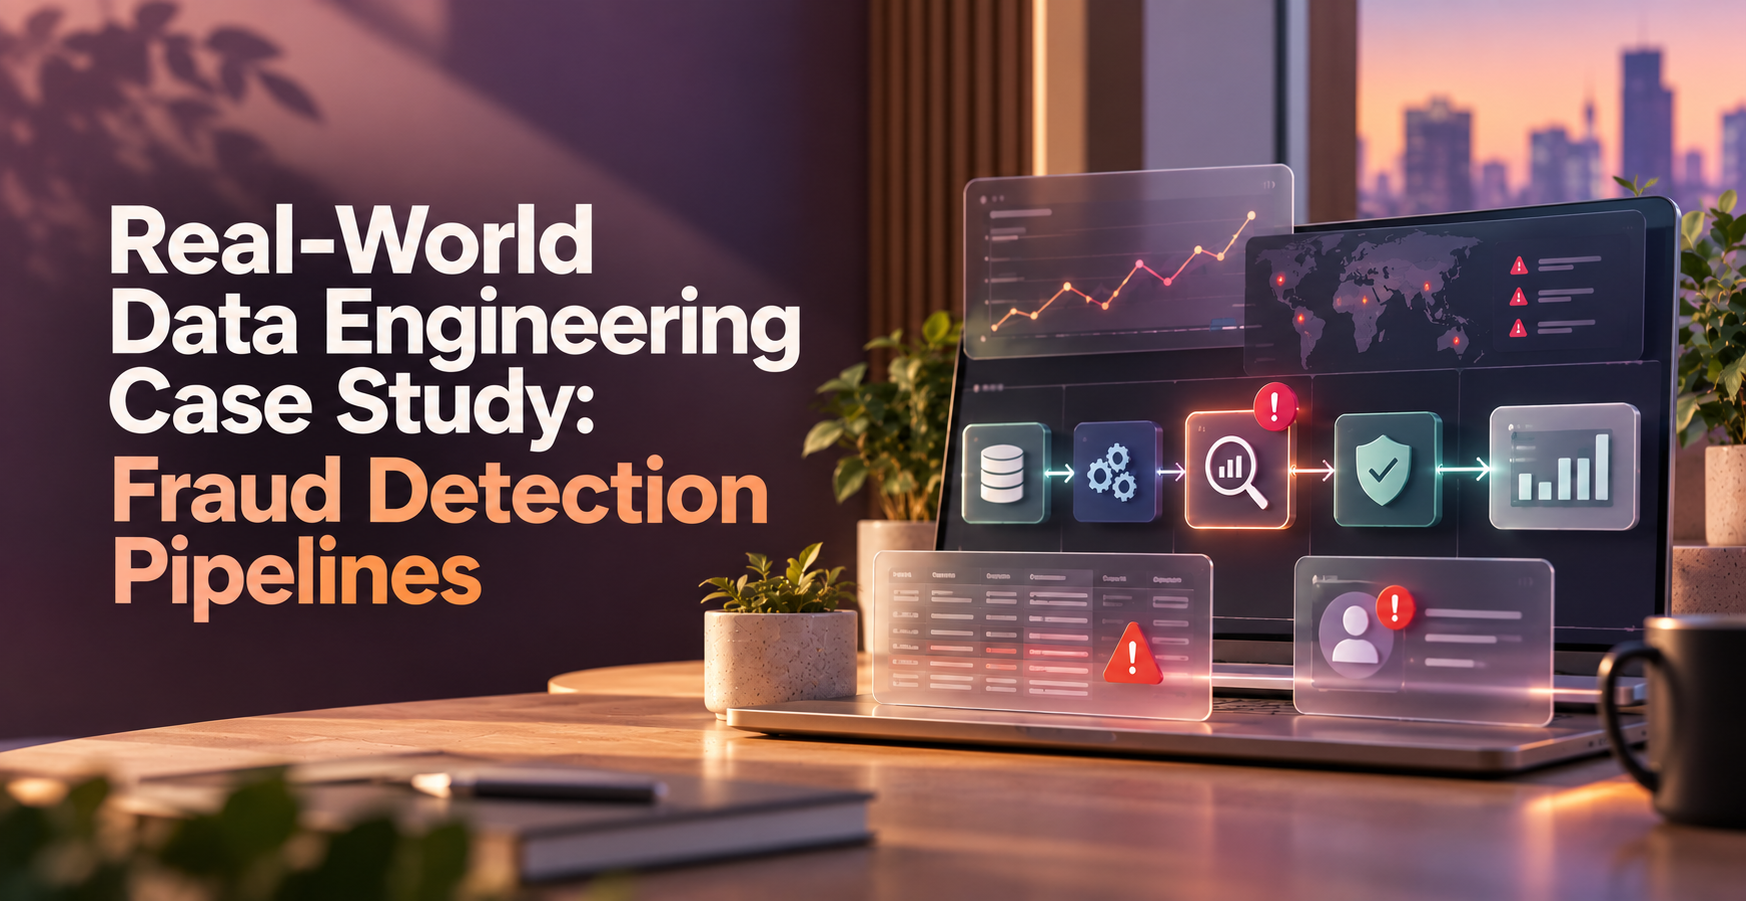
Payment event -> ingestion -> enrichment -> scoring -> decision -> audit record.
Capture events and build useful features
Kafka or Amazon Kinesis can ingest payment events. Flink or Spark can process them into features, such as recent account activity, spending totals, or device changes.
Enrichment can also pull merchant history, location signals, and account details. A feature store can make prepared features available for scoring. Each feature needs a timestamp because every source won’t update instantly.
Streaming and batch processing handle different jobs:
| Processing approach | Useful fraud workload |
| Streaming | Recent transaction counts and payment-time signals |
| Scheduled batch | Historical profiles, training datasets, and reporting |
Production fraud detection pipelines commonly need both. Match each feature’s update schedule to its decision value.
Score transactions and route the result
A rules engine can identify known conditions, such as a blocked account. A model-serving API can estimate fraud risk using multiple features.
Decision policy combines those outputs with thresholds and business constraints. High-risk payments might face rejection or review; lower-risk payments can proceed.
The payment service returns the decision within its deadline. Asynchronous reporting shouldn’t block checkout.
Record the transaction ID, feature timestamps, rule matches, model version, score, and final action. That record supports audits and later evaluation. Choose the stack around latency, scale, and existing systems.
How to keep fraud signals accurate as data changes
A healthy model can’t rescue broken inputs. Data engineering keeps the signals meaningful as traffic and customer behavior change.
Validate data and handle delayed fraud labels
Validate schemas, required fields, types, and currency formats at ingestion. Quarantine incompatible events rather than silently dropping fields.
Deduplicate events using stable identifiers. Make processing idempotent, so retrying an event doesn’t repeat its business effect.
Use event timestamps for time-window features. Define how late arrivals affect aggregates, and don’t silently rewrite an already-issued payment decision.
Chargebacks and investigation outcomes can arrive well after checkout. Join them to the original transaction ID, preserving label history and investigation status. A chargeback isn’t automatically a fraud label; use its reason and investigation outcome.
Training datasets must use features available at the original decision time. Google’s machine-learning engineering guidance addresses training-serving skew, where training data differs from production inputs.
Monitor quality, model behavior, and privacy
Monitor processing delay, queue backlog, error rates, feature freshness, and missing-value rates. Alert on unexpected schema changes or unusual event volume.
Watch the decision mix too. A sudden jump in declines could reflect an attack, a broken feature, or a policy change.
As labels mature, evaluate model performance by relevant segments. Data drift means input patterns changed; it doesn’t automatically prove the model became worse.
Protect payment and account data with access controls, encryption, data minimization, retention limits, and audit trails. Review fairness, including proxy effects, and avoid sensitive attributes in harmful or unlawful decisions.
What it takes to run fraud detection in production
Faster decisions leave less time for enrichment. Streaming infrastructure, model serving, and on-call support also carry operating costs.
Plan for failures, safe fallbacks, and clear ownership
Retry transient failures with limits. Send unprocessable events to a dead-letter queue for investigation and controlled replay.
Define a fallback policy when a feature source or scoring service fails. Depending on risk, that could use cached features, limited rules, or review. Blanket approval creates avoidable exposure.
Name incident owners and decide how they’ll reconcile delayed or replayed events. Replaying data mustn’t trigger duplicate customer-facing actions.
Before launch:
- Test dependency failures and fallback decisions.
- Prove replay won’t duplicate actions.
- Assign alerts and recovery ownership.
Fraud pipeline glossary
Event stream: A continuing sequence of events, such as payment attempts.
Feature: A model input, such as recent transaction count.
Feature freshness: How recently a feature reflects its underlying source data.
Feature store: A system for managing and serving features for training or prediction.
False positive: A legitimate transaction incorrectly flagged as fraudulent.
Precision: The share of flagged transactions that are truly fraudulent.
Recall: The share of all fraudulent transactions the system catches.
Data drift: A change in input patterns compared with an earlier reference period.
For guided practice, our free DE End-to-End Projects at Data Engineer Academy offer a place to build these skills.
Frequently Asked Questions
Does fraud detection need real-time data processing?
Payment authorization needs timely decisions, but every supporting task doesn’t need streaming. Use streaming for signals that must reflect recent activity during checkout. Batch jobs can prepare historical profiles, build training datasets, and support slower investigations without adding work to the payment request.
What is the difference between fraud rules and a machine-learning model?
Rules apply explicit conditions that people define. Models learn patterns from training examples and can combine signals that would be difficult to express manually. Many systems combine them so teams can enforce clear policies while using a model to estimate broader transaction risk.
How do data engineers handle delayed fraud labels?
Data engineers link later investigation results to original transactions using stable identifiers and maintain versioned label records. They distinguish unresolved payments from confirmed legitimate ones. Evaluation should compare transactions with sufficiently mature outcomes, so recent unlabeled payments don’t make performance look artificially strong.
Which tools can build a fraud detection pipeline?
Kafka or Kinesis can capture events, while Apache Flink or Spark can process them. Cloud storage supports historical data, and a feature store can serve prepared inputs. Start with your existing infrastructure and decision deadline rather than treating every named tool as mandatory.
How can a team reduce false declines without missing fraud?
Tune thresholds against reliable outcomes and examine precision, recall, and customer impact together. Review paths can handle uncertain cases without automatic rejection, but they need staffing and clear deadlines. Evaluate changes by relevant customer and merchant segments instead of relying on one aggregate score.
Build around the decision, then close the feedback loop
Effective fraud detection depends on reliable capture, fresh features, timely decisions, and careful monitoring. Model choice is one part of that system. Build on our free end-to-end projects at Data Engineer Academy to practice these connections.