Snowflake Snowpipe: Real-Time Data Ingestion Guide
Snowflake Snowpipe continuously loads new files from cloud storage into Snowflake without waiting for a scheduled batch job. It fits event data, application logs, IoT records, and near-real-time analytics where files arrive throughout the day. Snowflake Snowpipe is near real time, not true millisecond streaming, so expect freshness in minutes rather than instant row-by-row delivery.
A reliable pipeline starts with organized files, correct cloud notifications, and clear monitoring. The sections below cover setup, costs, production checks, and the right ingestion method for your latency target.
Key Points
- Snowpipe loads new cloud storage files into Snowflake as they arrive.
- Auto-ingest uses storage events, while the REST API submits file paths directly.
- File size, notification quality, and schema stability affect cost and freshness.
- Snowpipe works with files, while Snowpipe Streaming handles lower-latency records.
Quick summary: Snowpipe connects cloud storage events to a target table, so analytics tables receive completed files without a polling job. It works best when producers write orderly files, notifications reach Snowflake, and the team watches latency and failures.
Key takeaway: Snowpipe prevents many repeated file loads, but it cannot determine whether two differently named files contain the same event. Deduplication rules belong in your data model when source systems can resend data.
Quick promise: By testing file delivery, cloud notifications, access rules, and rejected-record handling together, you can find most production blockers before real reporting or customer-facing workloads depend on the pipeline.
What Snowflake Snowpipe Does and When to Use It
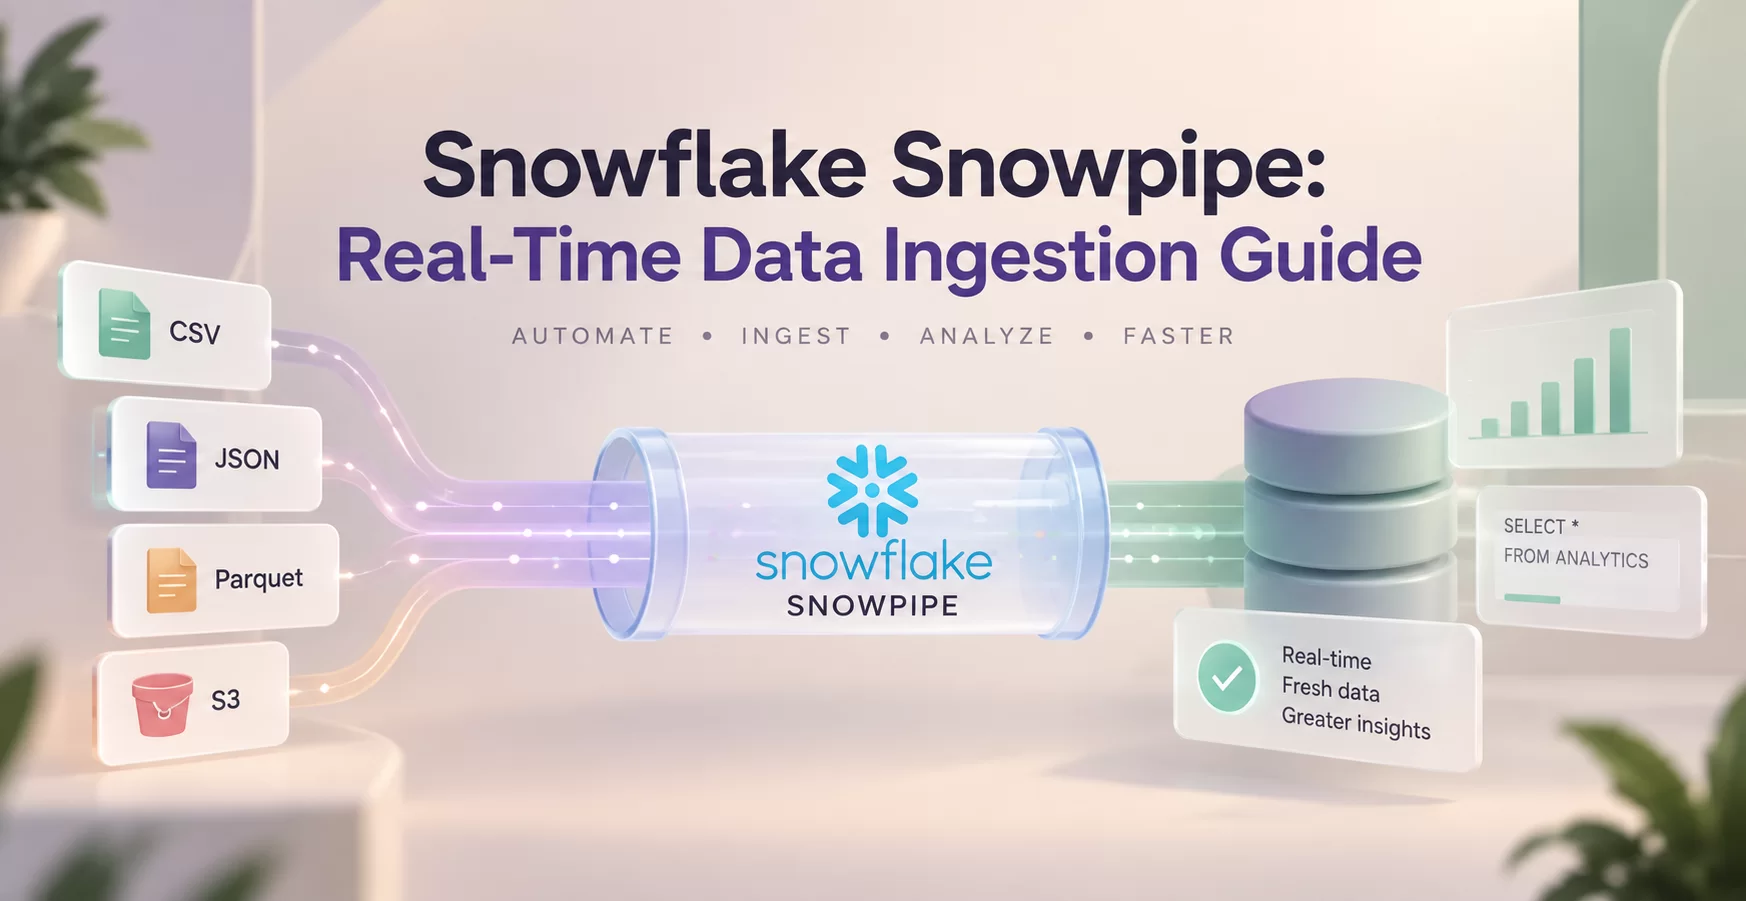
Snowpipe is Snowflake’s managed service for continuous file ingestion. A source application writes files to Amazon S3, Google Cloud Storage, or Azure Blob Storage. A cloud event notification tells Snowflake that a file exists, then a pipe loads it into a target table.
Behind the pipe, Snowpipe applies COPY INTO logic. You define the stage, file format, target table, and copy options once. Snowflake then loads matching files as notifications arrive.
Snowpipe suits JSON, CSV, Avro, Parquet, and XML files that arrive continuously. It is less suitable for sub-second event processing or huge planned backfills, where scheduled loading can cost less.
| Method | Typical latency | Input | Setup effort | Best fit |
| Snowpipe | Near real time | Files | Moderate | Continuous cloud files |
| Scheduled COPY INTO | Minutes to hours | Files | Low | Predictable batch loads |
| Snowpipe Streaming | Lower latency | Rows or records | Moderate | Fast event ingestion |
| Kafka connector | Low latency | Kafka topics | Higher | Existing Kafka platforms |
Choose Snowpipe when a producer already creates files in cloud storage and analytics can tolerate short ingestion delays.
How to Set Up a Snowpipe Pipeline Step by Step
Start with a small, known-good sample file. Exact commands vary by cloud provider and Snowflake account settings, so keep credentials out of SQL and application code.
- Create or select a database, schema, and warehouse for setup and validation.
- Create a file format that matches the incoming file structure and compression.
- Create an external stage that points to the storage bucket and folder.
- Create a target table with columns that match the landing data.
- Define a pipe with a COPY INTO target_table statement.
- Configure notifications for the stage path.
- Grant roles permission to use the database, schema, stage, pipe, and target table.
- Upload a sample file, then check that Snowflake loaded it.
For AWS, S3 event notifications commonly publish through Amazon Simple Notification Service or Amazon Simple Queue Service. Azure uses Event Grid, while Google Cloud uses Pub/Sub. Those services notify Snowpipe that a file exists. Snowpipe still reads the file directly from cloud storage.
Use this short setup checklist before enabling production traffic:
- Keep file names predictable and folder prefixes stable.
- Match file formats and compression to the pipe definition.
- Verify cloud permissions, encryption rules, and storage access.
- Avoid producing the same file under different names.
- Plan how schema changes will reach tables and file formats.
- Test malformed files before they reach production.
Auto-Ingest and REST API Ingestion: Choose the Right Trigger
Auto-ingest is usually the better choice when storage events are available. Cloud notifications trigger loading without an application calling Snowflake for every file. However, the event path needs correct permissions, prefixes, retries, and monitoring.
REST API ingestion works when an application or orchestration tool must submit file paths directly. It gives the caller more control, but that caller must handle retries and avoid repeatedly submitting the same file. Notification limits can also affect high-volume designs. Neither option changes Snowpipe’s core model, which loads files rather than individual messages.
Design Files and Tables for Reliable Loads
Stable folder structures and predictable names make failures easier to isolate. Use supported compression and sensible file sizes, since a flood of tiny files creates more notification and ingestion overhead.
Map columns explicitly when source order may change. Add metadata such as source file name and load time to help trace incidents. When source quality is uncertain, land raw data first, then transform it with SQL tasks or dynamic tables. Treat malformed records and schema drift as planned operational cases. Append-only landing tables are simpler, while merge-based models need careful deduplication rules.
Snowpipe Costs, Performance, and Reliability in Production
Snowpipe pricing uses Snowpipe credits. Cloud storage, event notifications, and downstream warehouse compute can add separate charges, so confirm current rates in Snowflake’s official pricing documentation before estimating a workload.
Tiny files, duplicate events, constant schema changes, and heavy downstream transformations can raise cost or delay availability. Batch many small records into larger files when the source allows it. Snowpipe tracks loaded files to reduce repeat loading, but downstream models still need idempotent logic when the same business event appears in separate files.
Set Production Controls Before Traffic Grows
Define a freshness target, retry process, and owner for every pipe. Keep a quarantine table or error path for rejected records. Also plan backfills, retention, role ownership, encryption, and access reviews before relying on the table for reporting.
Snowpipe does not replace data quality checks, business rules, or source-level recovery plans. A pipe can load a technically valid file that still contains incorrect values.
Monitor Load Health With Snowflake History and Alerts
Use Snowsight, pipe status, load history, copy history, and account usage views to inspect file activity. Track files received, files loaded, failed files, ingestion latency, duplicate notifications, and credit consumption.
Create alerts for stalled pipes, repeated parsing errors, growing backlogs, and missed freshness targets. When a load fails, check the file exists first. Then verify the stage path, cloud permissions, notification configuration, pipe definition, and load error message.
Secure Cloud Access and Data Ownership
Use a Snowflake storage integration or cloud-native identity configuration instead of embedding access keys in code. Limit permissions to the exact bucket, container, or prefix that the pipeline needs. Separate development, test, and production locations so a test notification cannot load into a production table.
Assign an owner for the pipe, landing table, cloud event configuration, and downstream transformation. Without clear ownership, failures often sit unresolved between data, platform, and application teams.
Snowpipe vs Snowpipe Streaming, COPY INTO, and Kafka
Snowpipe handles continuous file arrival. Snowpipe Streaming sends rows or records directly to Snowflake with lower latency. Scheduled COPY INTO fits periodic batches, while Kafka works best for teams that already operate Kafka clusters and need durable messaging.
| Option | Latency | Data format | Operational complexity | Typical use |
| Snowpipe | Near real time | Cloud files | Moderate | Logs, exports, IoT file drops |
| Snowpipe Streaming | Low latency | Rows and records | Moderate | Product events and telemetry |
| Scheduled COPY INTO | Scheduled | Cloud files | Low | Daily or hourly batch loads |
| Kafka with a Snowflake connector | Low latency | Kafka topic records | High | Managed event-stream platforms |
Kafka can write files to cloud storage before Snowpipe loads them, but extra layers need a clear reason. Avoid adding Kafka when cloud files already meet the freshness requirement.
Pick the Method That Matches Your Latency Target
Choose Snowflake Snowpipe for cloud files and near-real-time analytics. Choose Snowpipe Streaming when row-level latency matters. Use scheduled COPY INTO for planned batches and large backfills. Choose Kafka when stream management, replay, and topic-based routing are core platform needs.
Product limits, features, and pricing can change. Confirm current Snowflake documentation before building a production design.
Common Snowpipe Mistakes That Create Delays and Extra Cost
Missing cloud event permissions and incorrect stage URLs are frequent causes of stalled loads. Notifications must point to the right folder prefix, and the pipe must support the delivered format.
Tiny files, duplicate file creation, undocumented schema changes, and weak monitoring create avoidable cost. Test more than the happy path. Include delayed notifications, failed files, partial source outages, backfills, and permission changes. Loading raw data into a landing table makes recovery easier because you can reprocess data without asking the source system to recreate every file.
Put Snowpipe Into Practice
Snowpipe is a managed, file-based ingestion service for loading cloud storage files into Snowflake with near-real-time freshness. Its strongest use case is a steady stream of well-formed files, backed by reliable notifications and visible load history.
One-Minute Summary
- Define the freshness target before choosing an ingestion service.
- Use Snowpipe for continuously arriving cloud storage files.
- Build a small end-to-end test before connecting a production source.
- Secure the cloud integration with least-privilege access.
- Monitor load history, errors, latency, and credit usage before scaling.
Glossary
- Stage: A Snowflake object that points to internal or external file storage.
- Pipe: A named Snowpipe definition containing file-loading logic.
- File format: Settings that tell Snowflake how to parse a file.
- Auto-ingest: Event-driven loading triggered by cloud storage notifications.
- Event notification: A cloud message that reports a new file at a storage path.
- Snowpipe Streaming: Snowflake ingestion for lower-latency rows or records.
- COPY INTO: Snowflake SQL that loads staged data into a table.
- Schema drift: A source structure change, such as added or renamed columns.
- Ingestion latency: Time between file arrival and table availability.
Build these patterns in a guided cloud data engineering project with Data Engineer Academy, then apply them in interviews and production work. Continue with Snowflake data modeling, AWS event-driven pipelines, and data quality testing for stronger end-to-end pipeline skills.
FAQs
Is Snowpipe real-time?
Snowpipe is near real time, not true real time. It loads files after they arrive in cloud storage and Snowflake receives a notification. Actual freshness depends on file creation, event delivery, queue behavior, parsing, and load volume. Use Snowpipe Streaming when lower-latency row ingestion is required.
Does Snowpipe need a warehouse?
Snowpipe does not use your virtual warehouse for its managed file-loading compute. Snowflake bills Snowpipe credits for ingestion. However, you may use a warehouse for setup queries, transformations, data quality checks, merges, and downstream reporting after the file has loaded.
What file formats does Snowpipe support?
Snowpipe can load common structured and semi-structured file types. Typical choices include CSV, JSON, Avro, Parquet, and XML, provided the stage and file format match the source data. Compression settings also need to match the files that your producer writes.
What is the difference between Snowpipe and COPY INTO?
Snowpipe automates file loading as files arrive, while COPY INTO runs when you execute it. Both use file stages and similar loading rules. Scheduled COPY INTO is a practical choice for predictable batch windows, backfills, and workloads that do not need continuous ingestion.
Can Snowpipe load data from S3?
Yes, Snowpipe can load files stored in Amazon S3. Configure an external stage, storage access permissions, a pipe, and S3 event notifications. Amazon SNS or Amazon SQS can deliver the notification flow, depending on the architecture and Snowflake configuration.
How does Snowpipe prevent duplicate loads?
Snowpipe tracks loaded files to avoid loading the same file repeatedly. That protection does not replace business-level deduplication. If a source sends identical events in two separately named files, Snowpipe can load both. Add event IDs, source timestamps, or merge logic downstream.
When should I use Snowpipe Streaming instead?
Use Snowpipe Streaming when records need lower latency than file-based ingestion can provide. It sends rows or records directly rather than waiting for a completed file in storage. Snowpipe remains the simpler option when applications already generate files in S3, Azure Blob Storage, or Google Cloud Storage.
How do I troubleshoot a Snowpipe that is not loading?
Start by confirming that the file exists at the expected storage path. Next, validate the stage URL, cloud permissions, event notification prefix, and pipe definition. Review Snowflake load history and error messages for parsing failures, missing access, or an unsupported file format.